explained comic · 7 pages · your annotated copy
an educational manga explainer
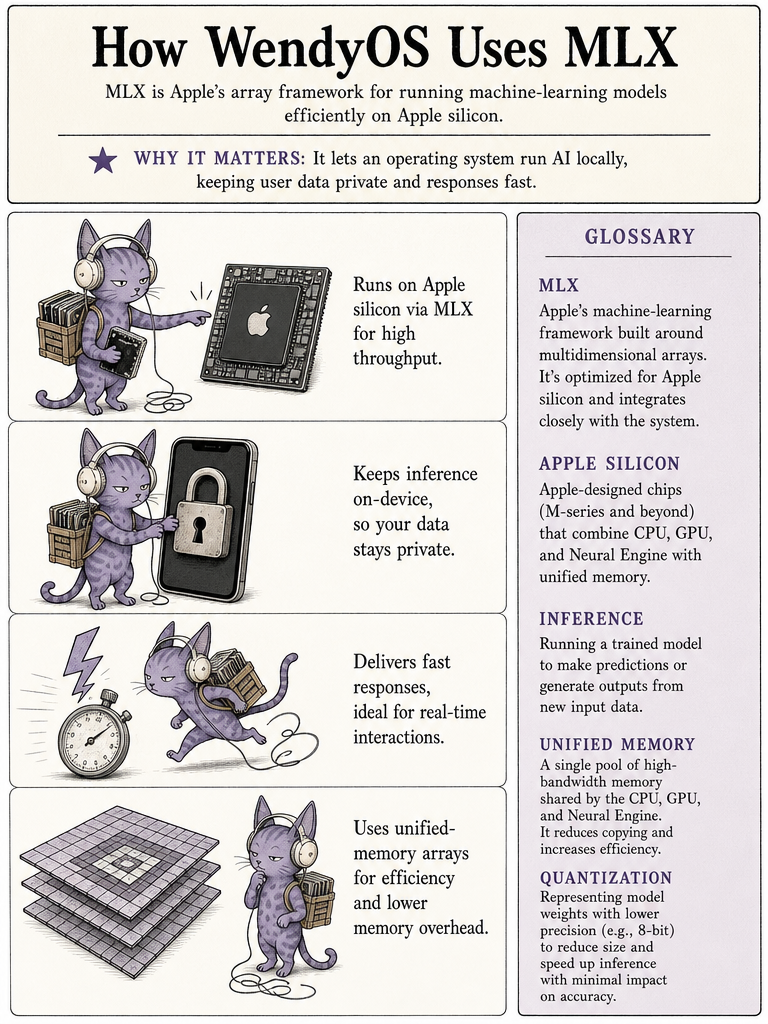
How WendyOS Uses MLX
comicexplain
session notes
kept private to your copy — sign in to add notes.
my take on page 1
key idea
MLX lets an OS run AI models locally on Apple chips for speed and privacy.
flip ↺
why this matters
On-device AI keeps personal data on your machine instead of shipping it to a server.
flip ↺
p. 1 · 7
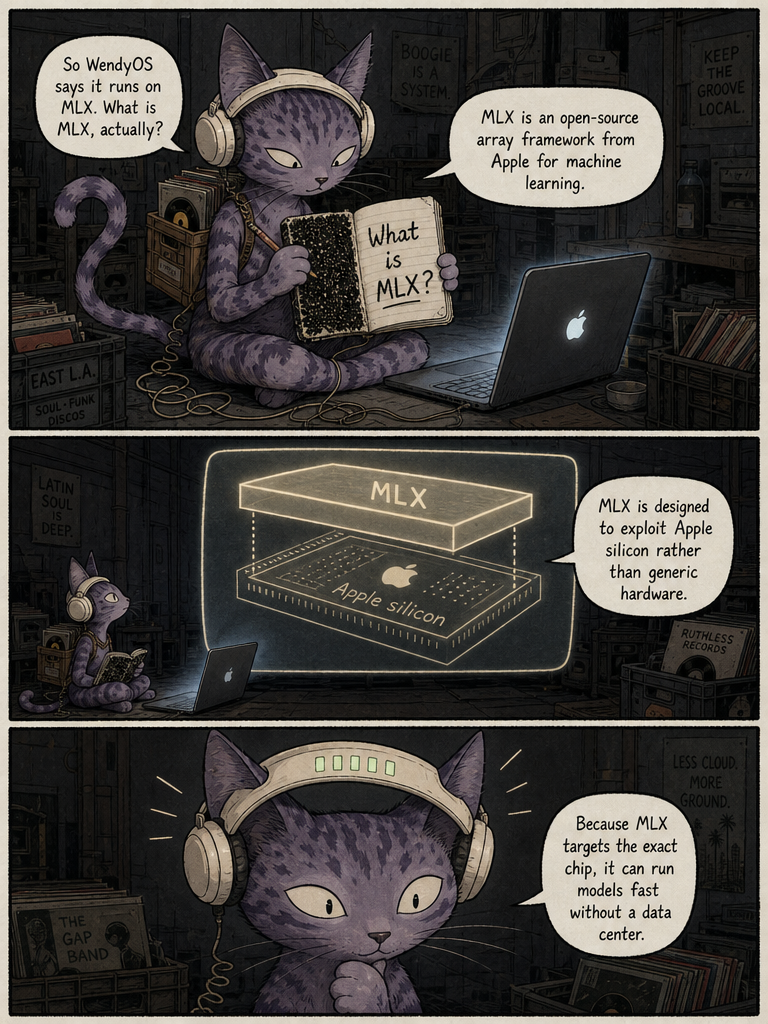
my take on page 2
key idea
MLX is Apple's array framework built to run ML models efficiently on Apple chips.
flip ↺
why this matters
Understanding the framework clarifies why WendyOS can do AI work without the cloud.
flip ↺
p. 2 · 7
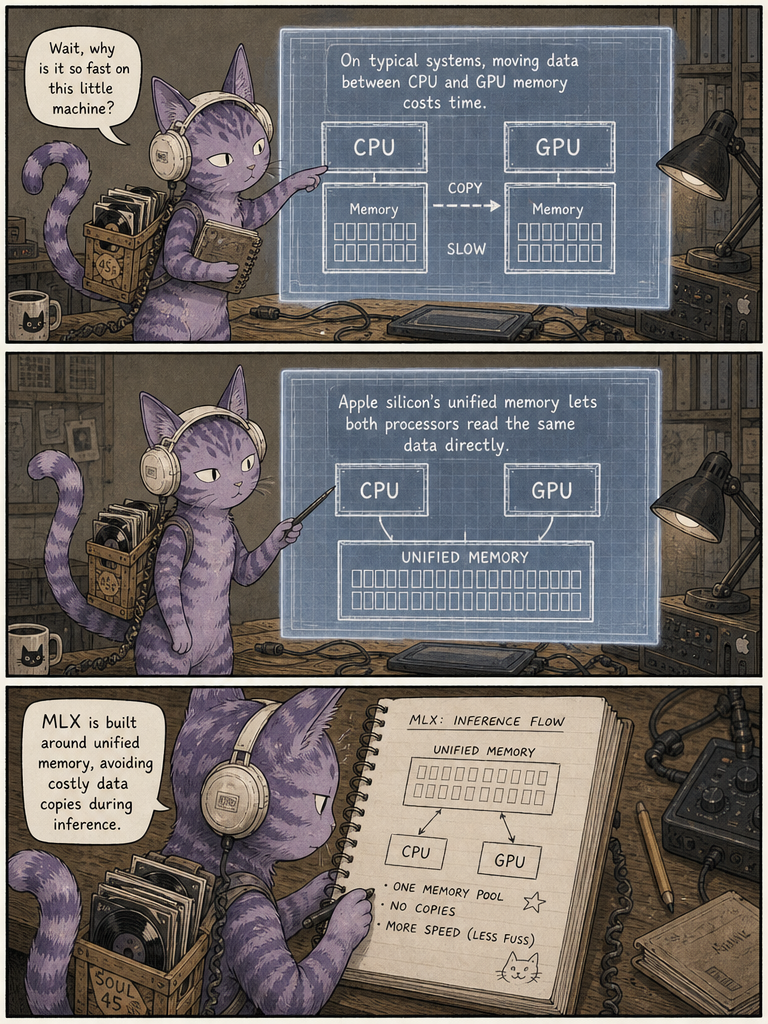
my take on page 3
key idea
MLX uses Apple's unified memory so CPU and GPU share data without copying.
flip ↺
why this matters
Avoiding memory copies is a big reason local models feel responsive on a laptop or phone.
flip ↺
p. 3 · 7
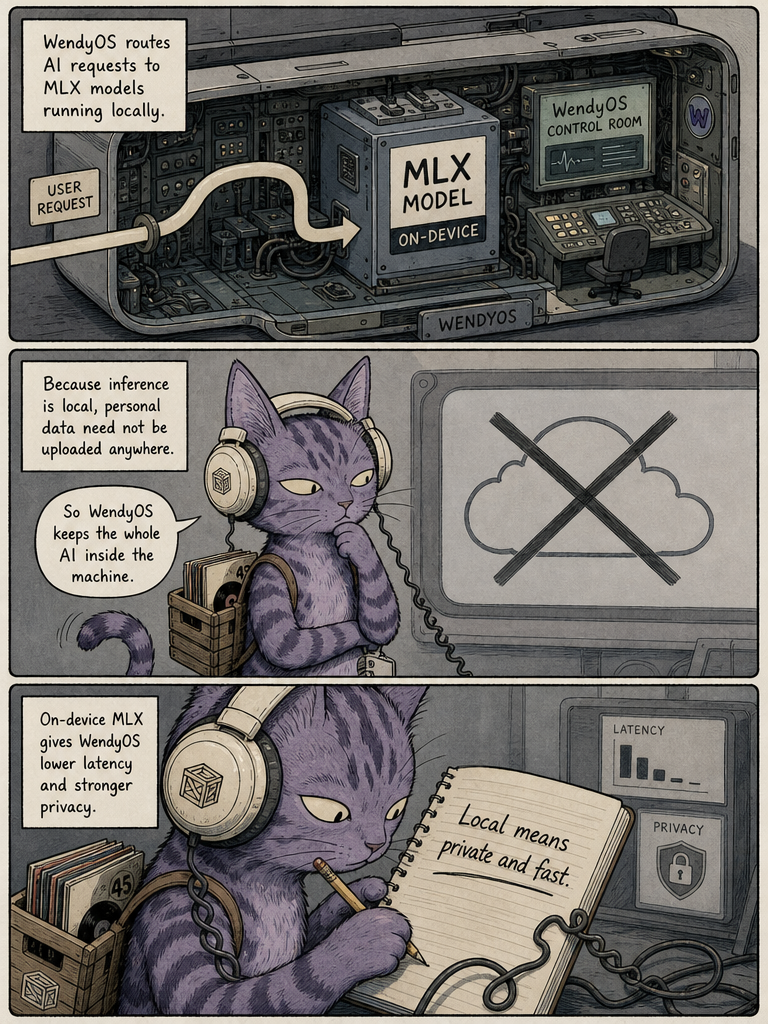
my take on page 4
key idea
WendyOS runs AI models on the device with MLX rather than in the cloud.
flip ↺
why this matters
Local inference means faster responses and data that never leaves your hardware.
flip ↺
p. 4 · 7
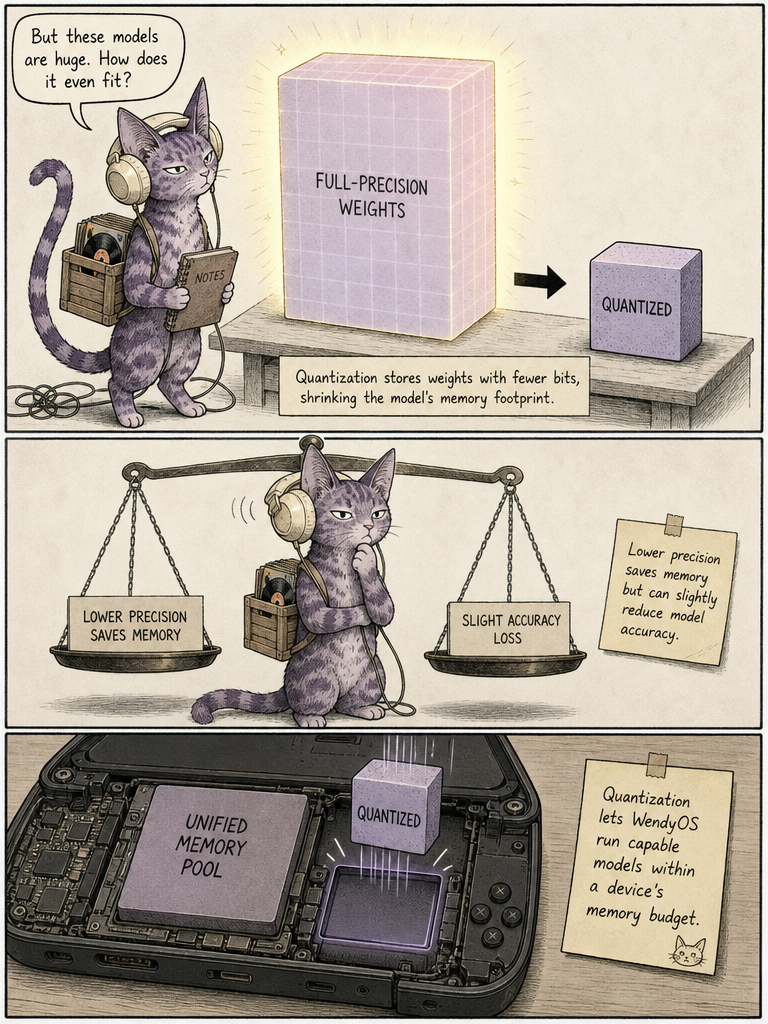
my take on page 5
key idea
Quantization shrinks model weights so large models fit in device memory.
flip ↺
why this matters
It is why a phone or laptop can run models that would otherwise need a big server.
flip ↺
p. 5 · 7
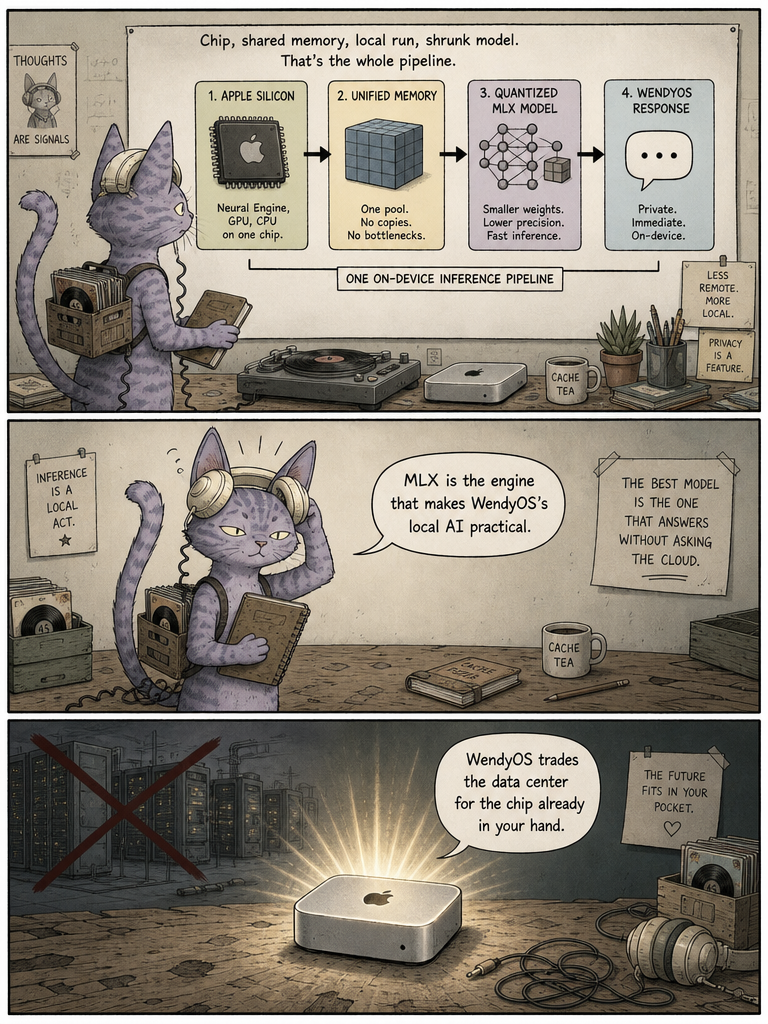
my take on page 6
key idea
MLX combines chip, unified memory, and quantization to power WendyOS's local AI.
flip ↺
why this matters
It shows how modern assistants can be both capable and private on everyday hardware.
flip ↺
p. 6 · 7
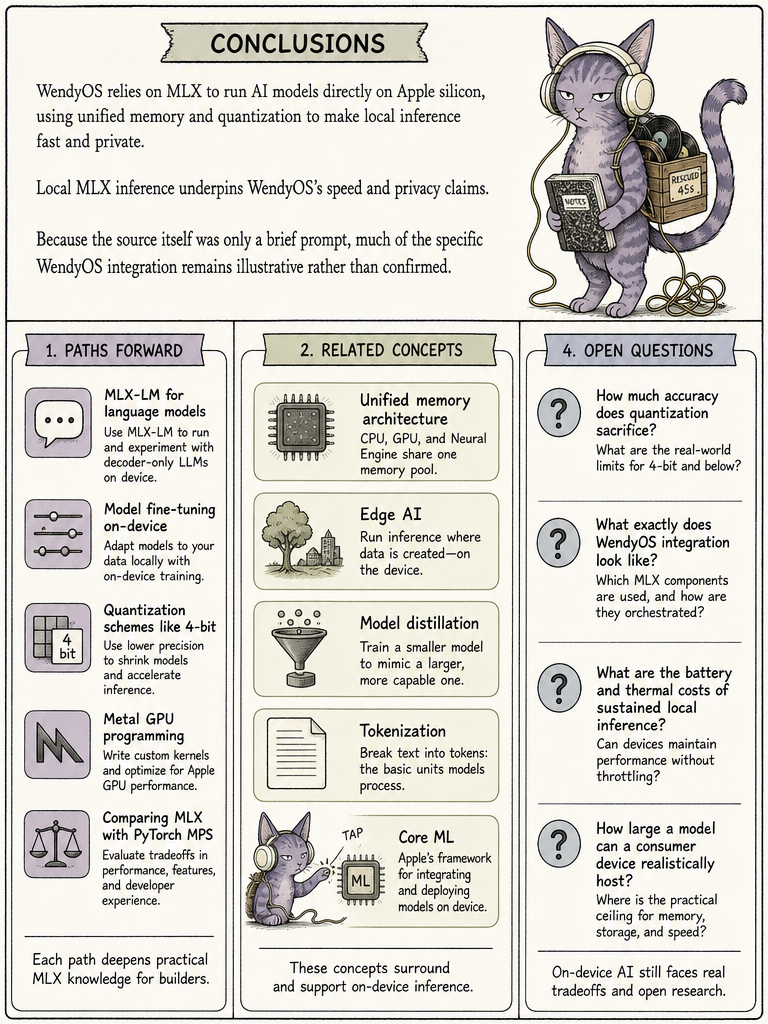
my take on page 7
key idea
Local MLX inference is powerful but still faces accuracy, battery, and capacity tradeoffs.
flip ↺
why this matters
Knowing the open questions helps readers judge on-device AI claims critically.
flip ↺
p. 7 · 7
flashcards · all 7
key idea
MLX lets an OS run AI models locally on Apple chips for speed and privacy.
click to flip ↺
why this matters
On-device AI keeps personal data on your machine instead of shipping it to a server.
click to flip ↺
card 1 · 7
one card per page — cycle through before you close the book.
index of key ideas
1MLX lets an OS run AI models locally on Apple chips for speed and privacy.
2MLX is Apple's array framework built to run ML models efficiently on Apple chips.
3MLX uses Apple's unified memory so CPU and GPU share data without copying.
4WendyOS runs AI models on the device with MLX rather than in the cloud.
5Quantization shrinks model weights so large models fit in device memory.
6MLX combines chip, unified memory, and quantization to power WendyOS's local AI.
7Local MLX inference is powerful but still faces accuracy, battery, and capacity tradeoffs.
comicexplain
paste a paper, get an annotated comic — pages appear in seconds.
front cover